
This is a viewer only at the moment see the article on how this works.
To update the preview hit Ctrl-Alt-R (or ⌘-Alt-R on Mac) or Enter to refresh. The Save icon lets you save the markdown file to disk
This is a preview from the server running through my markdig pipeline
图像 Summmarizer @:}一个受控制模糊图像 RAG 引擎
Tuesday, 06 January 2026
部分1-3 将受约束的模糊描述为抽象模式@. 本条将这些模式应用到工作图像分析管道中,以显示行动的原则_.
Onte: 仍在调整系统@. 但是现在有桌面版本和 CLI. 它工作得很好,但有些边緣可以平滑.
阅读指南
本篇文章服务多重目的@. @ navigate
- 建筑结构模式 → 参见 @"Wave ruil",}{"_Signal Contract} ",}"Ledger@"*
- OCR 详情 → 见 * OCR 管道 深技术分解
- CLI使用率 “→}跳转到“" ” 用它的CLI#:
- GUU 图形界面特征 → 见 @"#Desktop GUI"}部分
- 执行 执行情况 → 吉特胡布
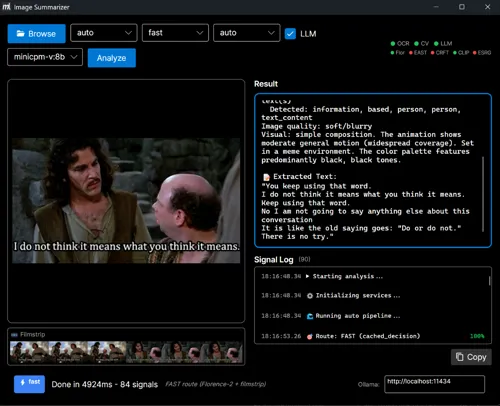
图像合成器是用于提取结构元数据{,} text},字幕{MSSK2和视觉信号的图像接收管道 wwad -基架构系统从快速的本地分析“(Florence -2ONNX)”升级为“视光LMS”,仅在必要时才提升至“视野LMs”。
关键原则 @:
- 无自主性 @(# 模特儿从来不会决定行刑路径@)#
- 没有自然状态@ - @ 语种状态 @ MS K1# 信号被键入 titled ,} not prosse)}
- 模型提出信号 ; 确定性政策 决定什么还在持续
图像放大仪显示,在不放弃确定性的情况下可以使用多式有限责任模型。 概率建议@, @% 确定论持续存在.
设计规则
- 模特儿从不消耗其他模型 '
- 自然语言从来不是状态
- 升级是决定性的门槛
- 每个输出都带有信任 *\ +\ 来源


[-=YTET -伊甸园字幕组=- 翻译:
它会做什么
管道提取来自RAG系统图像的结构化元数据*.}根据任何影像或动画的 GIF=,}它生产:}
- 已摘录的文本 @ MSK03-tier OCRMS K2Tesseract @ MPK3Florence-2ONNX @→VisionLLM 后退@)
- 彩色调色板 @(#computed@,}% 未猜到 @ )
- 质量衡量标准 @(_sharrpness,}模糊=,}暴露@)
- 分类类型 @(Photo,屏幕截图@,Digram_,MemeMS K4
- 动画图像的动作分析 @ (@ )#
- 可选标题 @(Florence-2}本地或视觉LLM□,}受计算事实制约
- 语义嵌入@ (_ 用于矢量搜索 @ MS K1} @
关键词是 结构式“. ”每个输出都有信任分数“, 来源归属”“MS K2 ”和证据指针“MSC3 ” 没有模型是真理的唯一源码“. ”
3-Tier OCR战略
深潜水OCR管道很复杂,足以证明它自己的文章有理。 3-Tier OCR管道 全部技术分类,包括USTZ,CRAFT,Real}-ESRGANMS K3CLIPMSKO4和胶片优化.
系统使用三-Tier升级策略来提取文本@:
| Tier | 方法MS K2速度 | 成本 | 最佳 | |
|---|---|---|---|---|
| 1 | 宇宙魔方 @ | @ @ ~50 @ ms @ I | @ free @ MPK3干净@ MS K4}高端-# contrastrast text @ O | @ |
| 2 | 佛罗伦萨 -=YTET -伊甸园字幕组=- 翻译: | |||
| 3 | 展望LLM | +#~1-5+%s @ | +%_$0.001-0.01+# | #Complication #/+QGarbled text #MS K6 |
智能路由
ONNX 文本检测 (东部, 花生鼠@, @ @ ~20-30 @ ms@ MS K2}决定最佳路径 @ I: @
- FAST 路线仅限(~100 @ms@)
- 豁免路线-=YTET -伊甸园字幕组=- 翻译:
- 平等路线: 多-框架分析 @+视觉LLM @MS K3s)#
支持ONNX模型
- 真实的#-ESRGAN@ : @ @ I4× @ super @ - @ 解析低端图像@ k3 @ legal images @ MPK4 @ ms@ MS K5} free) @
- CLIP:语义嵌入以搜索图像@(~100ms,free})
结果结果成果@: {~1.16_GB}本地的ONNX模型 处理没有 API 图像的 85%+.
见《在行动中》
动画分析

$ imagesummarizer demo-images/cat_wag.gif --pipeline caption --output text
Caption: A cat is sitting on a white couch.
Scene: indoor
Motion: MODERATE object_motion motion (partial coverage)
运动短语只有在得到光学流量测量和框架 deltas=;}作为支撑时才排放,否则系统会返回到中性描述器 {("}subtlemotion}",{"}camera movement}",} "}object traffy}MPK6}♪
Meme & 字幕提炼

$ imagesummarizer demo-images/anchorman-not-even-mad.gif --pipeline caption --output text
"I'm not even mad."
"That's amazing."
Caption: A person wearing grey turtleneck sweater with neutral expression
Scene: meme
Motion: SUBTLE general motion (localized coverage)
副标题“-Aver 框架重复”检测到下方“MS K1”的文字变化。 在以下框中, “, 加权亮像素 ” ((white/}) “Yellow text@) 更粗糙地” (MPK6)
框架脱法技术
对于带字幕的动画性GIFs来说,该工具为视野LLM分析创建水平框架条@.}三种模式针对不同的使用案例_:
文本@- @ 仅条形 "(NEW !" "MS K2" "I30×"象征性削减"
效率最高的模式只提取文本捆绑框@, 显著降低象征性成本 @:

$ imagesummarizer export-strip demo-images/anchorman-not-even-mad.gif --mode text-only
Detecting subtitle regions (bottom 30%)...
  Found 2 unique text segments
Saved text-only strip to: anchorman-not-even-mad_textonly_strip.png
  Dimensions: 253×105 (83% token reduction)
| “ | ” 接近“ | ” 维度“MS K2” 托肯斯 “ | ” 成本“MSC4” |
|---|---|---|---|
| +全框 @(10)+# | } @3000×185+ @MS K4+#~1500+#RSK6_High@ | +# | |
| OCR 脱衣舞? MS K1框架? | |||
| 文本@ - @ 仅条 | 253×105 | ~50 | 低 |
如何运作:+OpenCV 检测字幕区域 @(+Bottom @MS K2Q+30%),#门槛亮像素@(/iyellow text_),}根据文字修改来提取紧凑的捆绑框,}和复制品>.+ 视野LLM 只接收文本区域=,}保存所有字幕内容,同时删除背景像素□.}
OCR 模式条形 @(_text change only {-}93}将框架降为 <#2}框@):}

$ imagesummarizer export-strip demo-images/anchorman-not-even-mad.gif --mode ocr
Deduplicating 93 frames (OCR mode - text changes only)...
  Reduced to 2 unique text frames
Saved ocr strip to: anchorman-not-even-mad_ocr_strip.png
  Dimensions: 600x185 (2 frames)
运动模式条形 “(”键盘 运动推论“):”

$ imagesummarizer export-strip demo-images/cat_wag.gif --mode motion --max-frames 6
Extracting 6 keyframes from 9 frames (motion mode)...
  Extracted 6 keyframes for motion inference
Saved motion strip to: cat_wag_motion_strip.png
  Dimensions: 3000x280 (6 frames)
这样,Vision LLMs就能在单一的 API 调用中读取所有字幕文本@, 大幅提高memes和字幕内容的精度,同时尽量减少象征性使用 @.
为何不只说明一下呢?
这比 @ " @ 仅以疆界模型来说明它@ "} 出于同样的原因, X- @ ray tapes aluration @ MPK3{ 这个模式从未被要求填补空白 .} 它收到一份封闭的分类簿- 测量颜色\ MS K6} 跟踪运动=, 脱位字幕框@, OCR Information_ MSKO9} 并且只提供已经包含的基底框架$.} 当 GPT-4o 标注一个图像时 < k12 it\ '\ sguess n.> 当图像放大器做"," it\ MOK16\ 总结了已经存在的信号.}
波浪结构
该系统使用 wwad -基管 每个波都是独立的分析器 产生输入的信号.... 波的执行按优先排序 *\ ( lower number first\ MASK1\ \ {“,”和后来的波浪可以读取早期的信号“.”
执行令“:+Wave”“10+”在波浪@50+运行之前运行,
flowchart TB
    subgraph Wave10["Wave 10: Foundational Signals"]
        W1[IdentityWave - Format, dimensions]
        W2[ColorWave - Palette, saturation]
    end

    subgraph Wave40["Wave 40: Text Detection"]
        W9[TextLikelinessWave - OpenCV EAST/CRAFT]
    end

    subgraph Wave50["Wave 50: Traditional OCR"]
        W3[OcrWave - Tesseract]
    end

    subgraph Wave51["Wave 51: ML OCR"]
        W8[MlOcrWave - Florence-2 ONNX]
    end

    subgraph Wave55["Wave 55: ML Captioning"]
        W10[Florence2Wave - Local captions]
    end

    subgraph Wave58["Wave 58: Quality Gate"]
        W5[OcrQualityWave - Escalation decision]
    end

    subgraph Wave70["Wave 70: Embeddings"]
        W7[ClipEmbeddingWave - Semantic vectors]
    end

    subgraph Wave80["Wave 80: Vision LLM"]
        W6[VisionLlmWave - Cloud fallback]
    end

    Wave10 --> Wave40 --> Wave50 --> Wave51 --> Wave55 --> Wave58 --> Wave70 --> Wave80

    style Wave10 stroke:#22c55e,stroke-width:2px
    style Wave40 stroke:#06b6d4,stroke-width:2px
    style Wave50 stroke:#f59e0b,stroke-width:2px
    style Wave51 stroke:#8b5cf6,stroke-width:2px
    style Wave55 stroke:#8b5cf6,stroke-width:2px
    style Wave58 stroke:#ef4444,stroke-width:2px
    style Wave70 stroke:#3b82f6,stroke-width:2px
    style Wave80 stroke:#8b5cf6,stroke-width:2px
优先排序顺序 (Lower先跑 MS K1 10 MPK3 MASK4 NSK5 I50
这是 限制的模糊MOM 用于图像分析@: @% 多个提议方发布到共享基数 万岁 AnalysisContext@),和最后的输出集成 他们的信号#.
键波
- 文本相似性 (NEW): OpenCV EASTMS K2CRAFT 文本检测@(~5-20ms),确定路由决定
- 倾弃: 传统纯文本的宇宙魔方OCR (Tier MPK2
- MLOcrWife 移动“:Florence-2ONNX在本地运行”“(~200msMS K3 手持星型字体”“Z(Tier @2)”
- 佛罗伦萨当视野LLM为需要时, :当地 ML 字幕说明@' @t
- 杂质生活:Spell- check gateMS K2}决定升级路径
- 愿景村仅当早期波浪失灵或信号低置信度时,
波波订单上的注解{\fn方正黑体简体\fs18\b1\bord1\shad1\3cH2F1F2F}三高音 阶层 (Tesseract/Florence-2/Vision LLMMS K3是概念升级水平.个人波,如高级OCR或质量门。 精细 它们分别进行时间稳定性和质量检查 ,
信号合同
每个波都使用标准合同 生成信号
public record Signal
{
    public required string Key { get; init; }      // "color.dominant", "ocr.quality.is_garbled"
    public object? Value { get; init; }             // The measured value
    public double Confidence { get; init; } = 1.0;  // 0.0-1.0 reliability score
    public required string Source { get; init; }    // "ColorWave", "VisionLlmWave"
    public DateTime Timestamp { get; init; }        // When produced
    public List<string>? Tags { get; init; }        // "visual", "ocr", "quality"
    public Dictionary<string, object>? Metadata { get; init; }  // Additional context
}
这是“2 ” 部分在行动中的信号合同 “. ” 波不会通过自然语言相互交谈 ‘. ’ 他们发布共享环境的已键入信号$, ’,下游波可以查询这些信号.}
请注意 Confidence a single spective messical list has confirm {1.0但个人颜色百分率使用自信作为下游平衡的加权系数.
信任意味着 下游使用的可靠性“,”不是数学上的确定性“.” 决定因素信号是可复制的‘,’ 不是不可错的’-spell}-}检查对正确的名词是否正确,肯定是错误的。
确定论说明:{"_Terministic}" 意指特定运行时间没有抽样随机性和稳定结果;配置}.ONNX GPU 执行提供者可能引入小数字差异,,这对路由决定 <.#信号合同(thresworksMS K7 升级逻辑MSKO8仍然完全确定=.}
OCR 信号分类
为避免混乱 , 此处 @'}这是整个系统使用的 Canonical OCR 信号命名空间_:
| Q 描述 @ | |||
|---|---|---|---|
ocr.text |
+Tesseract @(_Tier#1)} | }原單一 -+Frame OCR # | # |
ocr.confidence 魔方信任得分= |
|||
ocr.ml.text |
mL OSCR单 MS K5Frame @ | ||
ocr.ml.multiframe_text @ |
多 -Frame GIF OCR @(P 首选动画片@)# | ||
ocr.ml.confidence @ |
佛罗伦萨-2 | 佛羅倫薩•-2信任得分 @ | |
ocr.quality.spell_check_score |
+OcrqualityWave @ | +确定性拼写@-_Check 比率= | # |
ocr.quality.is_garbled @ |
_OcrQIQVE# | _Boolean 升级信号@ | |
ocr.vision.text ? ? ? |
|||
caption.text @ |
_VisionLlmWave@ | _描述性标题 @MS K2}和 OCR)Q# | }分开 |
重要区别: ocr.vision.text 是 文本提取 在此期间, caption.text 是 场景描述 @(_Cappining).}两者都可能来自同一个视野LLM 调用{,},但服务的目的不同
最后文本选择优先权 最高至最低的):
ocr.vision.text-=YTET字幕组=- 翻译:ocr.ml.multiframe_textGIF=) {(} 佛罗伦萨 -2$GIF#MSK 2ocr.ml.text@(Florence-2}单人 -框架)ocr.text(Tesseract)
波浪界面
每个波都安装一个简单的接口@: @%
public interface IAnalysisWave
{
    string Name { get; }
    int Priority { get; }           // Lower number = runs earlier (10 before 50 before 80)
    IReadOnlyList<string> Tags { get; }

    Task<IEnumerable<Signal>> AnalyzeAsync(
        string imagePath,
        AnalysisContext context,    // Shared substrate with earlier signals
        CancellationToken ct);
}
缩略 AnalysisContext 是 协商一致空间 从 {2.} 波可以 :} <% 1 >
- 早期波浪的读取信号@: @%
context.GetValue<bool>("ocr.quality.is_garbled") - 访问缓存中间结果@:
context.GetCached<Image<Rgba32>>("ocr.frames") - 添加下游波浪能消耗的新信号
确定性基金会
彩色Wave 首先运行“ (” 优先级“ I10)” , 然后计算限制其它所有事物的事实@ MS K2 @
public class ColorWave : IAnalysisWave
{
    public string Name => "ColorWave";
    public int Priority => 10;  // Runs first (lowest priority number)
    public IReadOnlyList<string> Tags => new[] { "visual", "color" };

    public async Task<IEnumerable<Signal>> AnalyzeAsync(
        string imagePath,
        AnalysisContext context,
        CancellationToken ct)
    {
        var signals = new List<Signal>();

        using var image = await LoadImageAsync(imagePath, ct);

        // Extract dominant colors (computed, not guessed)
        var dominantColors = _colorAnalyzer.ExtractDominantColors(image);
        signals.Add(new Signal
        {
            Key = "color.dominant_colors",
            Value = dominantColors,
            Confidence = 1.0,  // Reproducible measurement
            Source = Name,
            Tags = new List<string> { "color" }
        });

        // Individual colors for easy access
        for (int i = 0; i < Math.Min(5, dominantColors.Count); i++)
        {
            var color = dominantColors[i];
            signals.Add(new Signal
            {
                Key = $"color.dominant_{i + 1}",
                Value = color.Hex,
                Confidence = color.Percentage / 100.0,
                Source = Name,
                Metadata = new Dictionary<string, object>
                {
                    ["name"] = color.Name,
                    ["percentage"] = color.Percentage
                }
            });
        }

        // Cache the image for other waves (no need to reload)
        context.SetCached("image", image.CloneAs<Rgba32>());

        return signals;
    }
}
展望有限责任有限公司后来收到这些颜色 制约因素若ColorWave计算到主要颜色是蓝色的 -,
升迁门
这里就是 受限制的模糊 闪光. Ocrquality Wave 是 限制 决定是否升级为昂贵的视野LLM=:
public class OcrQualityWave : IAnalysisWave
{
    public string Name => "OcrQualityWave";
    public int Priority => 58;  // Runs after OCR waves
    public IReadOnlyList<string> Tags => new[] { "content", "ocr", "quality" };

    public async Task<IEnumerable<Signal>> AnalyzeAsync(
        string imagePath,
        AnalysisContext context,
        CancellationToken ct)
    {
        var signals = new List<Signal>();

        // Get OCR text from earlier waves (canonical taxonomy)
        string? ocrText =
            context.GetValue<string>("ocr.ml.multiframe_text") ??  // Florence-2 GIF
            context.GetValue<string>("ocr.ml.text") ??             // Florence-2 single
            context.GetValue<string>("ocr.text");                  // Tesseract

        if (string.IsNullOrWhiteSpace(ocrText))
        {
            signals.Add(new Signal
            {
                Key = "ocr.quality.no_text",
                Value = true,
                Confidence = 1.0,
                Source = Name
            });
            return signals;
        }

        // Tier 1: Spell check (deterministic, no LLM)
        var spellResult = _spellChecker.CheckTextQuality(ocrText);

        signals.Add(new Signal
        {
            Key = "ocr.quality.spell_check_score",
            Value = spellResult.CorrectWordsRatio,
            Confidence = 1.0,
            Source = Name,
            Metadata = new Dictionary<string, object>
            {
                ["total_words"] = spellResult.TotalWords,
                ["correct_words"] = spellResult.CorrectWords
            }
        });

        signals.Add(new Signal
        {
            Key = "ocr.quality.is_garbled",
            Value = spellResult.IsGarbled,  // < 50% correct words
            Confidence = 1.0,
            Source = Name
        });

        // This signal triggers Vision LLM escalation
        if (spellResult.IsGarbled)
        {
            signals.Add(new Signal
            {
                Key = "ocr.quality.correction_needed",
                Value = true,
                Confidence = 1.0,
                Source = Name,
                Tags = new List<string> { "action_required" },
                Metadata = new Dictionary<string, object>
                {
                    ["quality_score"] = spellResult.CorrectWordsRatio,
                    ["correction_method"] = "llm_sentinel"
                }
            });

            // Cache for Vision LLM to access
            context.SetCached("ocr.garbled_text", ocrText);
        }

        return signals;
    }
}
升级的决定是 确定性如果拼写检查分数 @< @ @ 50%, @ 发送一个信号, 触发幻觉LLM. @ 没有概率判断@.}No#" @ maybe we should ask the LLM□"._ 只是个门槛%. @
行动升级

$ imagesummarizer demo-images/arse_biscuits.gif --pipeline caption --output text
OCR: "ARSE BISCUITS"
Caption: An elderly man dressed as bishop with text reading "arse biscuits"
Scene: meme
OCR得到了文字“;Vision LLM”提供现场背景@.每个波都贡献了它善于'.>的功能。
被约束的投标人
视觉LM波只有在早期信号显示它需要'Qs的时候才会运行 当它真的运行了,时
public class VisionLlmWave : IAnalysisWave
{
    public string Name => "VisionLlmWave";
    public int Priority => 50;  // Runs after quality assessment
    public IReadOnlyList<string> Tags => new[] { "content", "vision", "llm" };

    public async Task<IEnumerable<Signal>> AnalyzeAsync(
        string imagePath,
        AnalysisContext context,
        CancellationToken ct)
    {
        var signals = new List<Signal>();

        if (!Config.EnableVisionLlm)
        {
            signals.Add(new Signal
            {
                Key = "vision.llm.disabled",
                Value = true,
                Confidence = 1.0,
                Source = Name
            });
            return signals;
        }

        // Check if OCR was unreliable (garbled text)
        var ocrGarbled = context.GetValue<bool>("ocr.quality.is_garbled");
        var textLikeliness = context.GetValue<double>("content.text_likeliness");
        var ocrConfidence = context.GetValue<double>("ocr.ml.confidence",
            context.GetValue<double>("ocr.confidence"));

        // Only escalate when: OCR failed OR (text likely but low OCR confidence)
        // Models never decide paths; deterministic signals do (no autonomy)
        bool shouldEscalate = ocrGarbled ||
                              (textLikeliness > 0.7 && ocrConfidence < 0.5);

        if (shouldEscalate)
        {
            var llmText = await ExtractTextAsync(imagePath, ct);

            if (!string.IsNullOrEmpty(llmText))
            {
                // Emit OCR signal (Vision LLM tier)
                signals.Add(new Signal
                {
                    Key = "ocr.vision.text",  // Vision LLM OCR extraction
                    Value = llmText,
                    Confidence = 0.95,  // High but not 1.0 - still probabilistic
                    Source = Name,
                    Tags = new List<string> { "ocr", "vision", "llm" },
                    Metadata = new Dictionary<string, object>
                    {
                        ["ocr_was_garbled"] = ocrGarbled,
                        ["escalation_reason"] = ocrGarbled ? "quality_gate_failed" : "low_confidence_high_likeliness",
                        ["text_likeliness"] = textLikeliness,
                        ["prior_ocr_confidence"] = ocrConfidence
                    }
                });

                // Optionally emit caption (separate signal)
                var llmCaption = await GenerateCaptionAsync(imagePath, ct);
                if (!string.IsNullOrEmpty(llmCaption))
                {
                    signals.Add(new Signal
                    {
                        Key = "caption.text",  // Descriptive caption (not OCR)
                        Value = llmCaption,
                        Confidence = 0.90,
                        Source = Name,
                        Tags = new List<string> { "caption", "description" }
                    });
                }
            }
        }

        return signals;
    }
}
关键洞察力 : 视野LLM 文本具有信心 @ 0.95, @ 不是@1.0#. @ it' @% 1} 總比混亂的 OCRQ,}(但是它) MS K3 仍然概率=.} 下游團體知道這個@.} @ (_ why {0.95?} 預設前MSKO8} 設定為每個型號MS K9ipopilline},} [在 config}MSC11} 所記錄的精確值小於 拥有 a 值是 @'}%t *1.0.)}
Ledger: 受约束的合成
缩略 ImageLedger 将信号累积成结构化的下游消费区块 环境拖累 用于图像分析@: @%
public class ImageLedger
{
    public ImageIdentity Identity { get; set; } = new();
    public ColorLedger Colors { get; set; } = new();
    public TextLedger Text { get; set; } = new();
    public MotionLedger? Motion { get; set; }
    public QualityLedger Quality { get; set; } = new();
    public VisionLedger Vision { get; set; } = new();

    public static ImageLedger FromProfile(DynamicImageProfile profile)
    {
        var ledger = new ImageLedger();

        // Text: Priority order - corrected > voting > temporal > raw
        ledger.Text = new TextLedger
        {
            ExtractedText =
                profile.GetValue<string>("ocr.final.corrected_text") ??  // Tier 2/3 corrections
                profile.GetValue<string>("ocr.voting.consensus_text") ?? // Temporal voting
                profile.GetValue<string>("ocr.full_text") ??             // Raw OCR
                string.Empty,
            Confidence = profile.GetValue<double>("ocr.voting.confidence"),
            SpellCheckScore = profile.GetValue<double>("ocr.quality.spell_check_score"),
            IsGarbled = profile.GetValue<bool>("ocr.quality.is_garbled")
        };

        // Colors: Computed facts, not guessed
        ledger.Colors = new ColorLedger
        {
            DominantColors = profile.GetValue<List<DominantColor>>("color.dominant_colors") ?? new(),
            IsGrayscale = profile.GetValue<bool>("color.is_grayscale"),
            MeanSaturation = profile.GetValue<double>("color.mean_saturation")
        };

        return ledger;
    }

    public string ToLlmSummary()
    {
        var parts = new List<string>();

        parts.Add($"Format: {Identity.Format}, {Identity.Width}x{Identity.Height}");

        if (Colors.DominantColors.Count > 0)
        {
            var colorList = string.Join(", ",
                Colors.DominantColors.Take(5).Select(c => $"{c.Name}({c.Percentage:F0}%)"));
            parts.Add($"Colors: {colorList}");
        }

        if (!string.IsNullOrWhiteSpace(Text.ExtractedText))
        {
            var preview = Text.ExtractedText.Length > 100
                ? Text.ExtractedText[..100] + "..."
                : Text.ExtractedText;
            parts.Add($"Text (OCR, {Text.Confidence:F0}% confident): \"{preview}\"");
        }

        return string.Join("\n", parts);
    }
}
分类账就是 锁定锚 用CFCD的术语“.”表示,它延续了选择所遗留下来的东西 “,” 和LLM合成必须尊重这些事实.
升级决定
你见过两个地方的升级逻辑吗? OcrQualityWave 排放 信号信号 质量问题@; @% EscalationService 适用 政策和政策 这是故意分离 :
- Wave- 本地升级@:每波都透露其域内的事实@(e.g., "OCR是乱七八糟的□")
- 服务级别升级:
EscalationService使用全球阈值
缩略 EscalationService 执行部分的“1”模式 “:” substrate {→} 提议者 @ →} 限制器:
public class EscalationService
{
    private bool ShouldAutoEscalate(ImageProfile profile)
    {
        // Escalate if type detection confidence is low
        if (profile.TypeConfidence < _config.ConfidenceThreshold)
            return true;

        // Escalate if image is blurry
        if (profile.LaplacianVariance < _config.BlurThreshold)
            return true;

        // Escalate if high text content
        if (profile.TextLikeliness >= _config.TextLikelinessThreshold)
            return true;

        // Escalate for complex diagrams or charts
        if (profile.DetectedType is ImageType.Diagram or ImageType.Chart)
            return true;

        return false;
    }
}
每一个升级决定 确定性@:}同样的输入 相同的阈值 , 同樣的阈值*, 同一项决定MS K3* 没有LLM在升级逻辑上的判断=.
展望LLM Spirent:}证据限制
当视野有限责任公司确实运行了 , 它得到计算的事实 作为制约
private static string BuildVisionPrompt(ImageProfile profile)
{
    var prompt = new StringBuilder();

    prompt.AppendLine("CRITICAL CONSTRAINTS:");
    prompt.AppendLine("- Only describe what is visually present in the image");
    prompt.AppendLine("- Only reference metadata values provided below");
    prompt.AppendLine("- Do NOT infer, assume, or guess information not visible");
    prompt.AppendLine();

    prompt.AppendLine("METADATA SIGNALS (computed from image analysis):");

    if (profile.DominantColors?.Any() == true)
    {
        prompt.Append("Dominant Colors: ");
        var colorDescriptions = profile.DominantColors
            .Take(3)
            .Select(c => $"{c.Name} ({c.Percentage:F0}%)");
        prompt.AppendLine(string.Join(", ", colorDescriptions));

        if (profile.IsMostlyGrayscale)
            prompt.AppendLine("  → Image is mostly grayscale");
    }

    prompt.AppendLine($"Sharpness: {profile.LaplacianVariance:F0} (Laplacian variance)");
    if (profile.LaplacianVariance < 100)
        prompt.AppendLine("  → Image is blurry or soft-focused");

    prompt.AppendLine($"Detected Type: {profile.DetectedType} (confidence: {profile.TypeConfidence:P0})");

    prompt.AppendLine();
    prompt.AppendLine("Use these metadata signals to guide your description.");
    prompt.AppendLine("Your description should be grounded in observable facts only.");

    return prompt.ToString();
}
视野LM不应该声称“"vibrant colors” @"}如果我们计算灰度的话, “-}如果计算得出了灰度”,那么矛盾就是可检测到的 .}它不应该说“MS K5sharrpt details {"} 如果我们计算出低拉普拉西亚差异=--- 如果算得正确的话 我们可以拒绝输出,} 确定性基底率限制概率输出.
这些限制减少了幻觉,但不能消除它 -prompts 是建议 MS K1}不保证\ NSK2}真正的执法 通过信任加权和信号选择 在下游发生
产出文字
系统在提取最终文本时使用严格的优先顺序@: @%
static string? GetExtractedText(DynamicImageProfile profile)
{
    // Priority chain using canonical signal names (see OCR Signal Taxonomy above)
    //   1. Vision LLM OCR (best for complex/garbled)
    //   2. Florence-2 multi-frame GIF (temporal stability)
    //   3. Florence-2 single-frame (stylized fonts)
    //   4. Tesseract (baseline)

    var visionText = profile.GetValue<string>("ocr.vision.text");
    if (!string.IsNullOrEmpty(visionText))
        return visionText;

    var florenceMulti = profile.GetValue<string>("ocr.ml.multiframe_text");
    if (!string.IsNullOrEmpty(florenceMulti))
        return florenceMulti;

    var florenceText = profile.GetValue<string>("ocr.ml.text");
    if (!string.IsNullOrEmpty(florenceText))
        return florenceText;

    return profile.GetValue<string>("ocr.text") ?? string.Empty;
}
注注注注注释注注说明附注注注,注注 注注的注 注 注 注注说明注注附注注 注的注注 注注说注注的附注注说明,注 注,注说明的注说明说明注 注说明注说明 注注 注附注注的注释注 注 注 注注释注说明注释注的说明注,说明注的 注 注说明说明说明 注 注的说明说明,说明说明的附注 注注附注说明注附注的注附注 注 注注释说明注注释的注注释 注注注释注释注,的注, 注注,注释注附注附注注注释说明的说明 注说明 注的注释 注 注附注说明说明注释说明说明附注 注说明的注释注释注释说明 注注释注释 注说明注释注释的说明注释 注注释 注的附注注释注注释,注注释附注注附注注释的 注注脚注注注:此处选择一个源@,, 但账簿将所有来源都暴露为下游消费者可以检查的源代码 @. profile.Ledger.Signals 目睹刚果爱国者联盟的所有尝试和信心得分
每个来源都知道可靠性 :
- 展望LLM“: 最佳复杂场景”“, 图表 @, 图 @MS K3 信任$0.95, 高成本@)”
- 佛罗伦萨-2@: 适合天文字体@, 在本地经营 @MS K2 信任 *0.85-0.90, 无成本)
- 星体表决票@:#可靠而文字整洁 #(#信任不尽相同#,#确定性@)}
- Raw 宇宙魔方“:”基线后退“(”信任“<”“MSC3”用于模板化字体 ‘)’
位于视野LLM和宇宙魔方之间的知识的优先顺序为大多数图像提供了“"@sweet spot”\ @"}*—>比传统的 OCR,更便宜的云光 LMSZ.{
注意 @ : @% 此函数选择 1个 来源@,}但账簿曝光 全部 优先顺序是明智的默认设置@,}不是约束性套衣 @.}
甄选和解决冲突
以上优先链是当前执行的 @-a a simply fallback@.但架构支持添加拒绝规则, 如 config_-}驱动的政策.}(这里)'}*这是矛盾检测的模式 *#(}{尚未实施>,}但是有信号可以支持它=):}
// Pattern: Contradiction detection as policy rules
public static class SelectionPolicy
{
    public static string? SelectTextWithConstraints(DynamicImageProfile profile)
    {
        var visionText = profile.GetValue<string>("vision.llm.text");
        if (!string.IsNullOrEmpty(visionText))
        {
            // Rule: Reject if Vision claims text but deterministic signals say no text
            var textLikeliness = profile.GetValue<double>("content.text_likeliness");
            if (textLikeliness < _config.TextLikelinessThreshold && visionText.Length > 50)
            {
                // Contradiction detected - log and fall through
                profile.AddSignal(new Signal
                {
                    Key = "selection.vision_rejected",
                    Value = "text_likeliness_contradiction",
                    Confidence = 1.0,
                    Source = "SelectionPolicy",
                    Metadata = new Dictionary<string, object>
                    {
                        ["text_likeliness"] = textLikeliness,
                        ["vision_text_length"] = visionText.Length,
                        ["threshold"] = _config.TextLikelinessThreshold
                    }
                });
                // Fall through to OCR sources
            }
            else
            {
                return visionText;
            }
        }

        // Continue with priority chain...
        return profile.GetValue<string>("ocr.voting.consensus_text")
            ?? profile.GetValue<string>("ocr.full_text");
    }
}
同样的模式也适用于其他信号类型 @:
- 颜色矛盾@:_拒绝字幕, 声称@"#vibrant reds%"{如果
color.is_grayscale是真实的 - 尖锐自相矛盾@:_拒绝字幕,
quality.sharpness<阈值 - 类型自相矛盾@:_拒绝字幕 声称@"}a person * ]"如果
content.type是高置信度的图表图
选择层的关键属性 @:
- 优先连链@ : @ 每个源都有定义的后退顺序@ MS K1 @ not ad- @hoc check
- 上游优质大门: OCR 被接受 当确定性门上说它'时 它不是乱七八糟的 (<
- 扩展点@:_ 抵触规则是 config}-}驱动的 像任何其他政策一样版本
- 审计线索: 拒绝发出信号,显示观测值和阈值。
这是确定主义持续的地方 " 机械上成为真实的 MS K2 LLM提议
JSON 管道配置
通过JSON,, 管道是完全可配置的。 让波的组成明确且可以审计。
{
  "name": "advancedocr",
  "displayName": "Advanced OCR (Default)",
  "description": "Multi-frame temporal OCR with stabilization and voting",
  "estimatedDurationSeconds": 2.5,
  "accuracyImprovement": 25,
  "phases": [
    {
      "id": "color",
      "name": "Color Analysis",
      "priority": 100,
      "waveType": "ColorWave",
      "enabled": true
    },
    {
      "id": "simple-ocr",
      "name": "Simple OCR",
      "priority": 60,
      "waveType": "OcrWave",
      "earlyExitThreshold": 0.98
    },
    {
      "id": "advanced-ocr",
      "name": "Advanced Multi-Frame OCR",
      "priority": 59,
      "waveType": "AdvancedOcrWave",
      "dependsOn": ["simple-ocr"],
      "parameters": {
        "maxFrames": 30,
        "ssimThreshold": 0.95,
        "enableVoting": true
      }
    },
    {
      "id": "quality",
      "name": "OCR Quality Assessment",
      "priority": 58,
      "waveType": "OcrQualityWave",
      "dependsOn": ["advanced-ocr"]
    }
  ]
}
早期退出门槛值让昂贵的波浪跳过, 当廉价波浪已经达到高度信心时@. @这是部分预算管理 @1. @%
自动管道@ : @ 智能路由
缩略 auto 选择最佳处理路径@:
Image Analysis (OpenCV ~5-20ms)
    │
    ├── Is animated (>1 frame)?
    │   └── ANIMATED route
    │       ├── Has subtitle regions? → Text-only strip extraction
    │       ├── Minimal text? → FAST (Florence-2 only)
    │       └── Motion significant? → Motion analysis
    │
    ├── Has text regions (OpenCV detection)?
    │   ├── High contrast, clean text → FAST route (Florence-2, ~100ms)
    │   ├── Moderate confidence → BALANCED route (Florence-2 + Tesseract, ~300ms)
    │   └── Low confidence → QUALITY route (Multi-frame + Vision LLM, ~1-5s)
    │
    ├── Is chart/diagram (type detection)?
    │   └── QUALITY route → Vision LLM caption
    │
    └── Default → FAST route (Florence-2 caption)
路线绩效
| “ | ”路线“ | ”触发器,当 | 处理“MS K3”时(时间):“ | ”成本“ | ” |
|---|---|---|---|---|---|
| QAFST AST @ | 简单文本@,高对比度,标准字 { | 佛罗伦萨}-2只 | #~100MZ} < | 低~(本地) MS K11 | |
| @ | _BARBAR_普通文本 @MS K2}中度信任 @ | Florence_-2Q+Tesseract 投票@ | Z~300 | Low @(当地~)MSC11 | |
| @ | _QQQ# 质量% | } 图表,{,} 星形字体@,} 低置信 * | } 多功能-Frame 视觉LM | } @~1-5} @ MS K10 中度□(′API})} NSK13 | |
| @ | ANTION MASSK1}GIFs 字幕: # | }Text}-}只穿短裙 +*电影机 * | }#~2-3* * | 中間APIQK9} |
自动选择路径
$ imagesummarizer anchorman-not-even-mad.gif --pipeline auto --output visual
[Route selection...]
  Image: 300×185, 93 frames
  Text detection: 15 regions found (bottom 30%)
  Subtitle pattern: DETECTED
  → Selected ANIMATED route (text-only filmstrip)

[Processing...]
  MlOcrWave: Extracted 10 frames → 2 unique text segments
  Text-only strip: 253×105 (83% token reduction)
  VisionLlmWave: Processing filmstrip...

[Results - 2.3s total]
Text: "I'm not even mad." + "That's amazing."
Caption: A person wearing grey turtleneck sweater with neutral expression
Scene: meme
Motion: SUBTLE general motion
路由决定是确定性的,记录在审计信号中*:
{
  "routing": {
    "selected_route": "ANIMATED",
    "reason": "subtitle_pattern_detected",
    "text_regions": 15,
    "frames": 93,
    "decision_time_ms": 18
  }
}
CLI: 使用它
基本用法
# Use auto pipeline (smart routing - recommended)
imagesummarizer meme.gif --pipeline auto

# Fast local caption with Florence-2 ONNX (~200ms)
imagesummarizer photo.jpg --pipeline florence2

# Best quality: Florence-2 + Vision LLM
imagesummarizer complex-diagram.png --pipeline florence2+llm

# Extract text only (three-tier OCR)
imagesummarizer screenshot.png --pipeline advancedocr

# Motion analysis for GIFs
imagesummarizer animation.gif --pipeline motion

# Process a directory with visual output
imagesummarizer ./photos/ --output visual
信号收藏
只要求您需要的信号 。
# Minimal metadata (fast)
imagesummarizer image.png --signals "@minimal"

# Alt text for accessibility
imagesummarizer image.png --signals "@alttext"

# Motion analysis
imagesummarizer animation.gif --signals "@motion"

# Full analysis
imagesummarizer image.png --signals "@full"

# Custom wildcard patterns
imagesummarizer image.png --signals "color.dominant*, ocr.text, motion.*"
| 集 | 信号MS K2使用大小写 | ||
|---|---|---|---|
@minimal @ |
_ 身份_ .} @*,Q质量 @.#sharrpness * | }快速配置仅@ | * |
@alttext |
}标题 @._text,ocr. text@, 彩色#.主題* @ | 无障碍 *# | |
@motion @ |
# 动议_.} @* | 动画分析 | |
@full 完全分析= |
|||
@tool |
优化子集 @ | MCP}/ 航空= |
真正的 JSON 输出
$ imagesummarizer princess-bride.gif --output json
{
  "image": "princess-bride.gif",
  "duration_ms": 1838,
  "waves_executed": ["ColorWave", "OcrWave", "AdvancedOcrWave", "VisionLlmWave"],
  "text": {
    "value": "You keep using that word.\nI do not think it means what you think it means.",
    "source": "ocr.voting.consensus_text",
    "confidence": 0.95
  },
  "escalation": {
    "triggered": true,
    "reason": "text_likeliness_above_threshold",
    "threshold": 0.4,
    "observed": 0.67
  },
  "signals": {
    "color.dominant_1": { "value": "#1a1a2e", "confidence": 1.0 },
    "ocr.quality.spell_check_score": { "value": 0.82, "confidence": 1.0 },
    "ocr.quality.is_garbled": { "value": false, "confidence": 1.0 },
    "motion.type": { "value": "static", "confidence": 0.95 }
  }
}
每个字段都有出处 . escalation 区块显示 为什么 视野LLM被称为.
动议分析

$ imagesummarizer demo-images/alanshrug_opt.gif --pipeline motion
Motion: SUBTLE general motion (localized coverage)
Direction: up-down
Magnitude: 0.23
交互式模式
$ imagesummarizer
ImageSummarizer Interactive Mode
Pipeline: advancedocr | Output: auto | LLM: auto
Commands: /help, /pipeline, /output, /llm, /model, /ollama, /models, /quit

Enter image path (or drag & drop): F:\Gifs\meme.gif
Processing...
I'm not even mad. That's amazing.

Enter image path: /llm true
Vision LLM: enabled

Enter image path: /model minicpm-v:8b
Vision model: minicpm-v:8b
桌面图形界面
用于视觉探索@,桌面应用程序提供 @:
- 拖放% & @ 放下接口用于即时分析的 :
- 实时信号日志@ : @ 观察波在真实时间执行@ MS K1_ 充满信心的彩色
- 示范状况指标@:#交通灯光系统@🟢ready},}{🟡} 正在处理 *,
- 动动的 GIF 预览: 见胶片制作和框架提取
- 信号检查员: 单击任何信号以查看完整的来源和元数据
- 管道选择器: 自动@/florence @2/QQQquality}/motion 模式之间的切换
- 出口备选办法: 复制信号为 JSON, 保存胶片*, 导出文字
桌面圖形使用者介面顯示了架构的視覺化@—你可以看到究竟哪個波浪是,}他們發出什麽訊號{,, 路由決定是如何作出的?
CLI 将所有复杂情况暴露为简单选项@. 您可以在不理解波结构的情况下切换输油管{,}模式_,和输出格式=.}
图案出现的地方
| @ | @ part @ MPK1 @ 樣式 @ I | @ 图像放大器执行@ MS K3 @ | |
|---|---|---|---|
| 1 | 受限制的模糊 @ | _ColorWave 计算事实@;_VisionLlmWave尊重它们 @MS K2}# | |
| 2 | 限制的模糊MOM | +多波发布到分析Context@;+WaveOrchestrator坐标 @ | +# |
| 3 | 环境拖累 | 图像Ledger 积累突出特征 @; 信号数据库缓存结果@ |
相同模式@. @ 不同域 @ .} 相同的规则@ MS K2 概率建议@, @% 确定论持续存在.
你得到的
- RAG-\ _# 即时输出“: 结构化的JSON 具有自信分数” @, 不流传
- 本地端@- @% 1 第一处理@ :Florence-2ONNX在本地经营 @(~200msMS K3}大多数图像无需使用API费用
- 智能路由自动输油管选择最佳路径 @(_FAST#/BALANCED}/UALITY)
- 调制效率:Text-只有條件能取得 GIF 字幕的@30×象征性减少
- 可审计裁决每一次升级都有明确的原因
- 型号@-不可知性用于 OpenAI 或不改变建筑的人类学 : Swap Ollama
- 由内容捆绑在一起@:_相同图像@=}同样的分析,}即使重新命名为 @MS K3#SQLite 缓存 \ ,}{2-10>%s hitness}
- 桌面图形界面: Drag-和- 与实时信号可视化的连接
- MCP 服务器模式: 与支持示范背景协议的任何LLM 整合 * @(\Claude 桌面@, 等{.)}
- 基于 API 的信号@- @%: 只要求您需要使用通配符模式或收藏
成本多少
- 认知管理间接费用“:你必须理解信号合同”“, 浪浪重点”和“升级逻辑”,然后才写出一个单波‘ .’ 。
- 具体纪律每个信号键都需要一个清晰的定义 每一个信任分数都需要一个基本原理 你无法手握-波
- Per- 微波复合“: ” 每个波都有自己的配置“, 边缘情况”", 和失败模式@. 调试发生在波层”, 而不是管道级别 @.
- 测试表面更多元件表示更多的测试@. @ mock 上下文 @,}确认信号#,}校验升级路径 @MS K4}
- 预付投资: 您定义波浪, 信号MS K2 和分类账结构 在您看到结果前@.
这不是快速路径@. @ it'}如果您只需要图片画廊的字幕, 需要在比例上理解可审计图像%;#超权值的话值得使用可靠的路径@ . @ title: group
失败模式和如何处理它们
{\fn黑体\fs22\bord1\shad0\3aHBE\4aH00\fscx67\fscy66\2cHFFFFFF\3cH808080}失败模式 {\fnarial black\fs12\fscy110}What happens {\fnmicrosoft yahei\fs24\shad1\3cHFF8000\4\b0}它是如何处理的{\r\fntahoma\fs14\1cH0000FF00}
| ------------------------------ | ------------------------------------ | -------------------------------------------------------------------------------------------------------------------------------------------- |
| 吵闹的GIF @+SSIM 重复@+}投票一致 *{+}文本=-}只提取条纹
| OCR还垃圾 |Tesseract 在标准字体上失败 @|Spell-检查门检测@<#MSSK4正确 *→升至佛罗伦萨}-2Z→愿景LLM,如果仍然贫穷的话|
| APPI高成本 @| @% 太多云光 LLM 呼叫@|Florence}(佛罗伦萨)-2ONNX 手持 @MS K3}本地 @(~200ms), @ text-}只有条可以减少 GIFs 的代号 @MSKO7}{|#
| 幻觉 @|}LLM 声称文字是{'}(这里有)|}信号使得上面显示的矛盾检测@(}#pattrtan 能够比较下游消费者vision.llm.text Vs 和 content.text_likeliness |
| 随着时间的推移而变化的管道 “|”新波浪加盖了“,”阈值,调整过“MS K2” 调适了“内容” “|” (contimulation *-) “hash caching ” {+ } 每个信号的完整出处 ‘+’ 版本跟踪 |}
| 模型返回无 视觉超时或空响应 | 下降链 MS K2 视觉LM → 佛罗伦萨 -2 * @→ 宇宙体投票 → RO OCRQ; 优先秩序确保优雅的降解 *NSK8
每个失败模式都有确定性反应 . 没有静态降解
大图像@ : @ modal 图解 RAG
重要背景:图像放大器 图像摄取管道 用于 LuidRAG 生态系统的
本篇文章的重点是从图像中提取结构化信号@.}但是当与其他摘要集合起来时,真正的力量就会显现出来
- DocSummamer 缩写器 - 结构化文件分析 @(PDFs, 标记@,代码#)
- 数据合成器 - 表格数据剖析@(CSV,数据库 @)
- 图像合成器 @ ( @ this article\ MPK1 @ @ @ I-图像和动画分析
当连接在一起 卢西德拉格 这三条管道已启动 modal 图形 RAG:
Document → DocSummarizer → Structured signals
    ↓
Images → ImageSummarizer → Structured signals
    ↓
Data → DataSummarizer → Structured signals
    ↓
    ↓ (all signals)
    ↓
LucidRAG Graph Builder → Multi-modal knowledge graph
    ↓
Query → Multi-modal retrieval + constrained generation
为什么这重要:传统RAG将图像作为不透明的小块处理,这些小块被标注为 @. multi-modal 图RAG将影像视为 第一级-类信号源 与 text {,} 数据 ,} 和其他图像的键入关系@.} 相同确定性原则 @,} 不同比例=.}
如果您能够从图像中提取结构化信号 {(} this article}),}文档 {(}\ MSK3}DocSummamer 缩写器, 和数据 数据合成器), 您可以构建一个知识图, 每个节点都携带源头 每个边缘都有自信的分数.
很快即将: 完整的 Lucidrag 集成显示这些管道是如何组成多Q-modal 图RAG询问}.}相同的建筑原理*,统一的信号基质基底 *.
结论结论
架构结构为“: ” 每个波都是独立的 “, ” 每一个信号都输入了“MS K2 ” “每个信号都是决定性的 . ” Florence-2 提供快速本地分析“, ” Vision LLM 处理复杂的案例“MSKO6 ” 但是两者都没有操作不受限制的“MSSK7 确定性信号总是固定输出“MSQK8 ”
自首篇文章发表以来 ,系统发生了显著变化
- 佛罗伦萨-2ONNX融合 切除API成本及延缓度@(~200 @%ms 本地 vs @~1-5} 云端 @ ) *
- 文本@ - @ 仅薄膜 GIF 字幕的象征性减少
- 自动输油管道 根据图像特性选择最佳路线
- 信号收藏 简化通用例 @ (@ @ altext@ MS K1} @ I@_ promotion @ MPK3 @ @ *@ @ minimmal @ )}
- 桌面图形界面 提供有实时信号可视化的拖放分析@ - @ 和-}
仅OCR输油管—}以其三-QQTerreacal abliance_, mosK3Frame投票MS K4,胶片优化MSKO5和文本{-只有条纹提取@—}变得非常复杂,足以证明它有详细的文章<.> 看 OCR 愿景一体化 完整技术解析指南*.
如果您能用 OCR 噪音 @, @ stylized fonts@,}动画框,}和幻觉-}易見字幕{—}你可以用任何概率性组件做此操作 *.}
工作代码=.}没有抽象的图案吗?
资源资源资源 资源和资源资源资源
仓库库
- LucidRAG 仓库 - 完整源代码
CLI 工具
核心图书馆
- DocSummerizer * . 图像 -核心图像分析库
- README 阅览图书馆 - API 文件@,波结构_,和集成指南
- 《建筑结构指南》 @ -波,信号 @ , 升级 @,缓冲
- 管道文件 -Auto,平衡□,质量},Florence2+llm
- OCR 愿景一体化 -Routing,电影剧MS K2象征性经济学
- 动议分析 -GIF框架提取,动作探测
- 信号参考 - 信号目录 @, 收藏@,通配符语法
相关条款
- DocSummamer 缩写器 - 使用类似模式的文件分析管道
- 数据合成器 “-”数据剖析,采用相同的确定论“-”第一种方法。
系列丛书
-=YTET -伊甸园字幕组=- 翻译: | ---- | ------------------------------------------------------------------------- | ------------------------------- | | 1 | 受限制的模糊 @|单元件 @ |# | 2 | 限制的模糊MOM | 多元件| | 3 | 环境拖累 |Q时间 /Q内存 | 4 | 这篇文章#) | 波浪结构@, @% 模式 | | 4.1 | 3-Tier OCR管道 -=YTET -伊甸园字幕组=- 翻译:
下一頁@ :_ part *\ MS K1} 将展示图像的缩写@ ,} DocSummamer 缩写器,和 数据合成器 以 LucidRAG\ . 组成多-modal 图形 RAG
所有部件都沿着相同的变数 : 建议的概率元件.